Getting Started with Keboola
Build your first working data pipeline in Keboola: load 10,000 octopus sightings, join them with SQL, deliver a spreadsheet, run it on a schedule, and ship a map app.
Somebody claims that an octopus has been recorded near almost every coastline on Earth. You have the data to check — a century of ocean records — but it is spread across four files, none of which answers alone. That is the situation this guide starts from, and swap octopuses for orders or sensors and it is the ordinary one.
The question the arc answers:
How close to your coast does an octopus live — and how deep down do they really go?
You have 10,000 recorded octopus sightings from 1900 to 2026 — 201 species, each point with coordinates and, for almost half of them, a depth. The sightings file alone can plot dots. What it cannot tell you is who and where in any human sense: it names species by a numeric ID and says nothing about oceans or depth zones, so the moment the question becomes “which octopus, which ocean, how deep”, the file stops answering. Three small lookup tables — species names, depth zones, ocean basins — hold the missing halves, and joining them is the whole trick.
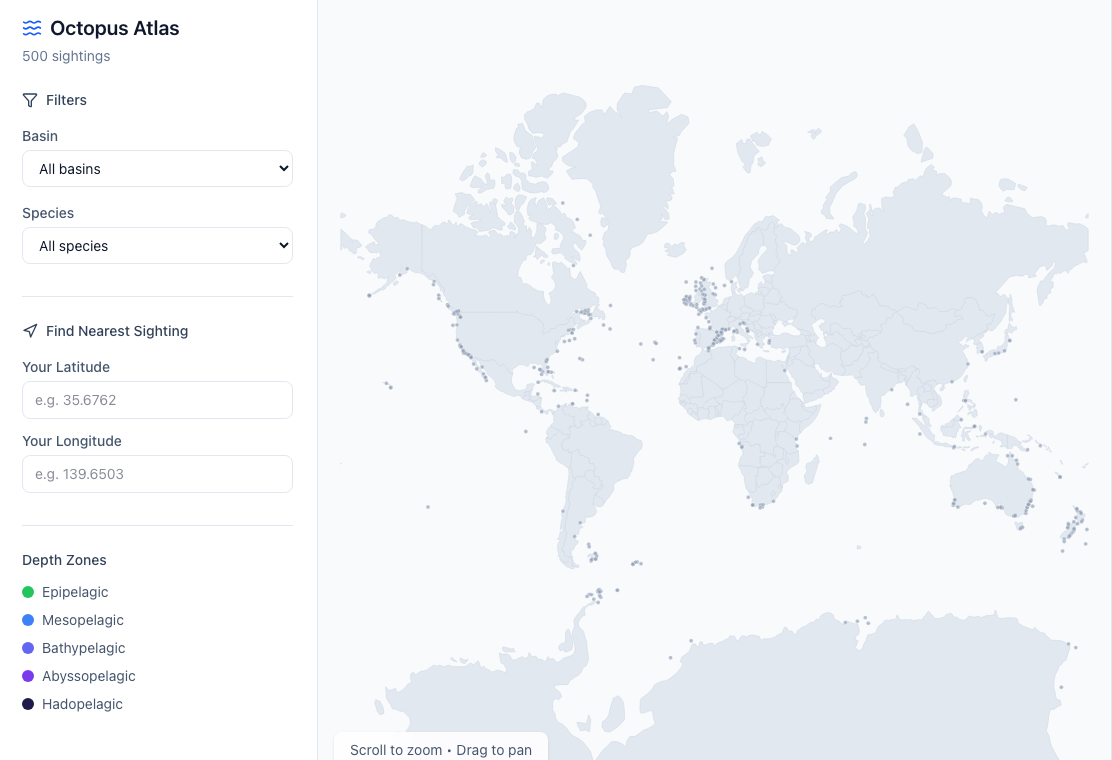
In under an hour you will have a table that answers all of it, delivered to a spreadsheet, rebuilt every morning without you, and an interactive map where you type your own coordinates and get the nearest recorded octopus — a working, scheduled pipeline with an app on top, not an exercise. Most steps are one Kai prompt: copy it, watch it build, check the result; every step also has the click-through version. Everything happens in the browser; nothing needs installing, and a free project covers all of it — no sales call.
What you will build
Section titled “What you will build”| Phase | What happens | Keboola calls it |
|---|---|---|
| Load | four CSV files, fetched from a URL, become four tables | a data source connector |
| Transform | SQL joins them into one wide table | a transformation |
| Deliver | that table appears in a Google Sheet | a data destination connector |
| Automate | all of it runs daily, in order, and emails you if it breaks | a flow |
| Answer | a map of every sighting, with a “how close to me?” field | a data app |
The joined table is the one someone would actually read: every sighting with its species by name, the ocean basin it sits in and — where a depth was recorded — its depth zone, down to a dumbo octopus (Grimpoteuthis challengeri) recorded 4,838 meters below the surface. It is not a demo — this is the mechanism a production project uses, just smaller. And this is where it ends up:
Before you start
Section titled “Before you start”- A project. Step 1 gets you one. The Free Plan covers this guide’s work — the whole arc uses roughly six minutes of job runtime — as long as your project has runtime minutes available.
- Basic SQL. One
SELECTwith a couple ofJOINs. If you have never written SQL, the queries are given in full and you can paste them — in both Snowflake and BigQuery form, since which one you need depends on your project. - A Google account, for the delivery step. If you would rather not connect one, skip step 4 and build step 5’s flow with two phases instead of three — loading and transforming on a schedule is a real pipeline, just one that keeps its result inside Keboola.
Nothing needs installing. Everything below happens in the browser — and if you take the Kai tabs, the whole build needs maybe fifteen minutes of your attention.
Two ways to do every step
Section titled “Two ways to do every step”Steps 2 through 6 open with a Do it with Kai tab — copy the prompt, watch it build, check the result — and a Do it yourself tab with every click written out, for when you want to see the mechanics. Only two things stay yours either way: creating the project (step 1) and the Google authorization in step 4.
Kai asks before it changes anything — expect one approval dialog per object it creates; questions that only read do not ask. If the confirming gets tiring, click Always allow, or pre-approve tools in tool permissions.
The Kai Agent button sits in the top bar; an organization admin switches the feature on, and Free Plan projects get a monthly message allowance — see Get started with Kai. And once you have seen the five pieces, they collapse: the last page shows the whole arc as one prompt.
The steps
Section titled “The steps”- Get a Project — create or join one, learn what a project and a stack are, find your way around.
- Get Your Data In — pull the four sample files into Storage with a connector, and understand buckets, tables and stages. One Kai prompt, run included.
- Transform Data — the SQL that turns species IDs into names and places every sighting in its ocean and depth zone. One Kai prompt builds and runs it.
- Deliver the Answer — push the result to a Google Sheet with a data destination connector. You authorize; one Kai prompt does the rest.
- Run It on a Schedule — run the whole thing in order, on a schedule, with notifications. Kai wires the flow; the schedule is two clicks.
- Build the App — a map of every sighting with a “how close to me?” field, described to Kai in one sentence and published with one button.
- Where to Go Next — what to learn next based on what you actually want to do, including how to drive Keboola from an AI assistant, an IDE, or your terminal.
Read them in order. Each step ends with a link to the next, and every page states what it assumes so you can also land on one directly and catch up.
Going further
Section titled “Going further”Optional side trips, once the main path makes sense. None of them are needed to finish the arc:
- Load from Google Sheets and Load from a Database — load from a source that needs credentials, rather than the public URL step 2 uses.
- Use a Workspace — develop and test SQL against a copy of your data before committing it to a transformation.
- Ad-Hoc Data Analysis — explore arbitrary data in a Python or R notebook rather than building a pipeline.
- Development Branches — change a running project safely, review the diff, then merge.
If you are planning a rollout, not learning the tool
Section titled “If you are planning a rollout, not learning the tool”This guide is for one person building one pipeline. For introducing Keboola to a team — project architecture, a data model, naming conventions, governance — start with Platform Onboarding instead.
Next: Get a project →